A LAMMPS job on QuickMDSim can ask for up to 64 cores. The machine exists only while the job runs. Extra cores always cost more per second. They do not always finish sooner. We timed that, on two systems, plus one NVIDIA L4.
Two choices, one credit wallet
The Run control is still one picker. CPU is 1, 2, 4, 8, 16, 32, or 64 cores. GPU is one NVIDIA L4, on Pro. GPU is not “64 cores with a graphics card.” It is one GPU, and it burns 12 CPU-units per wall-second. A 64-core CPU job burns 64.
Eight cores is a different machine than four. The charts below do not connect those two classes into one line.
What we measured
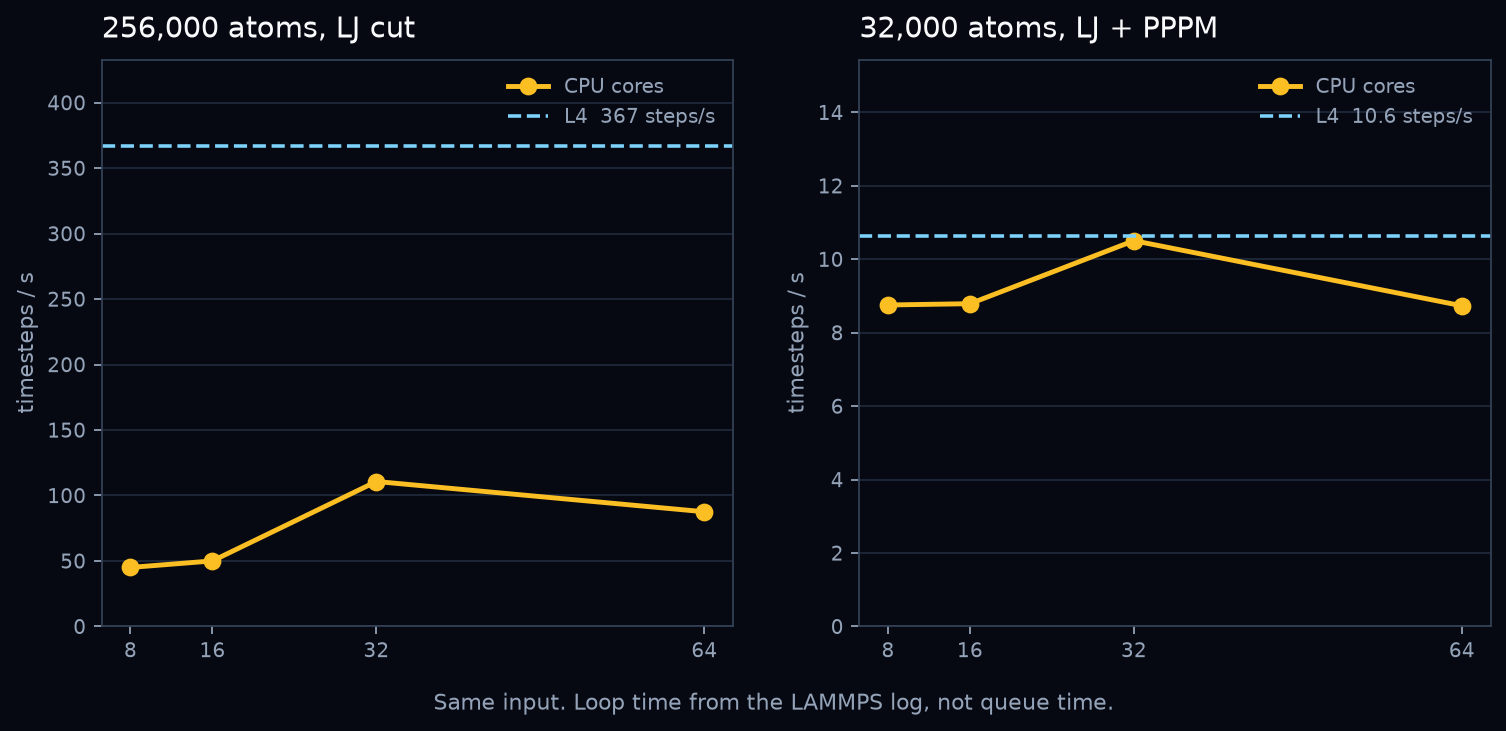
Rates are timesteps per second while LAMMPS was actually stepping, not time spent waiting for a machine. The same input ran at every size.
256,000 atoms, short-range LJ
FCC Lennard-Jones liquid, reduced density 0.8442, lj/cut 2.5,
NVE, timestep 0.005. 40×40×40 cells, 256,000 atoms. Neighbor skin 0.3,
rebuild every 20 steps.
- 8 cores: 45.1 steps/s. Pair was 70% of the loop.
- 16 cores: 50.0 steps/s. Almost no gain. Communication rose to 41%.
- 32 cores: 110.7 steps/s. Best CPU. 2.5× the 8-core rate, not 4×.
- 64 cores: 87.6 steps/s. Slower than 32. Communication was 76% of the loop.
- L4: 366.8 steps/s. 3.3× the best CPU, 8.1× the 8-core rate.
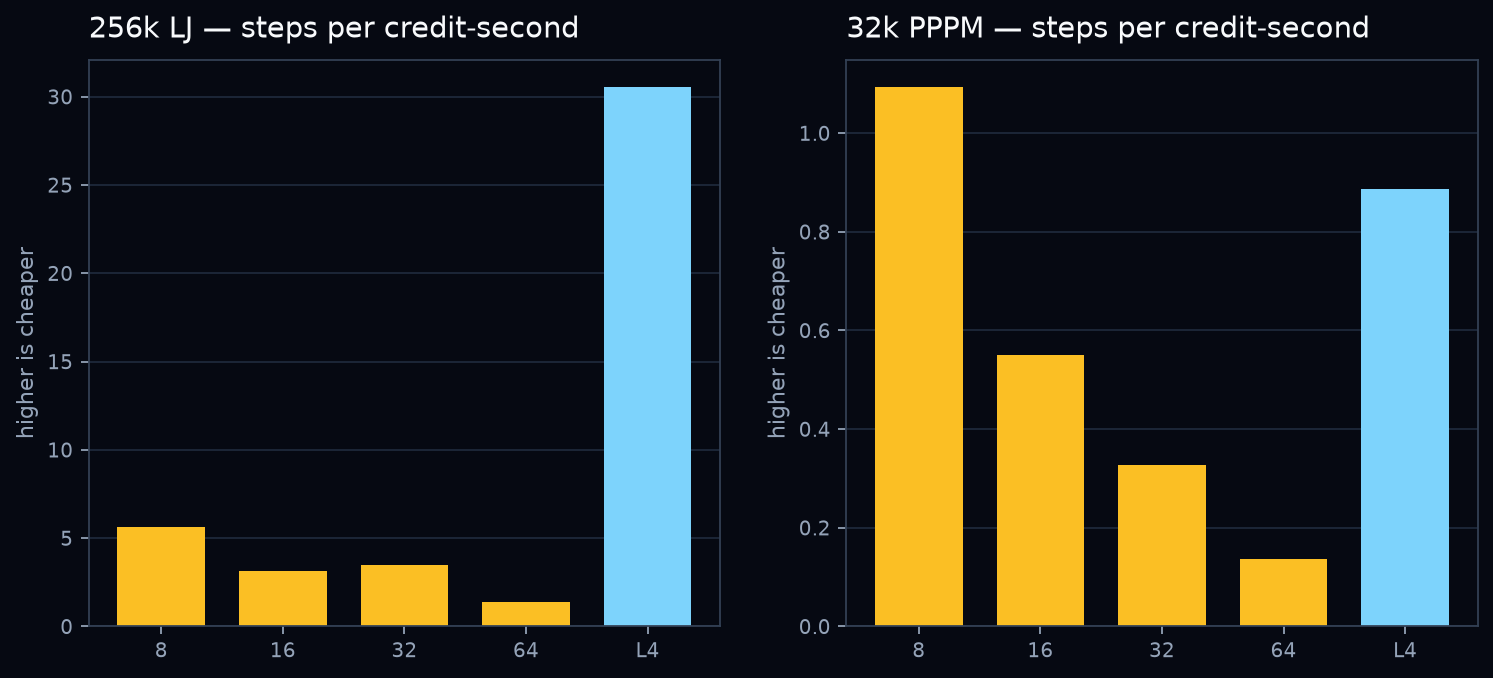
On credits the L4 is the cheap one here: 30.6 steps per credit-second, against 5.6 on 8 cores and 1.4 on 64. Sixty-four cores was the most expensive way to run this script, and not the fastest.
Every size, including the L4, printed the same final thermo line (step 1000, T = 0.545, PE = −6.097). Same trajectory, not just a run that finished.
32,000 atoms, LJ plus PPPM
Same density, charges of +1 and −1 alternating (net charge 0),
lj/cut/coul/long 2.5, pppm 1.0e-4. LAMMPS
built a 120×120×120 grid. The long-range part was 95% or more of the
loop at every size. The FFT on this GPU is not a fast one. That is the
result.
- 8 cores: 8.75 steps/s.
- 16 cores: 8.79 steps/s.
- 32 cores: 10.5 steps/s. Best CPU, and only 20% above 8 cores.
- 64 cores: 8.73 steps/s. Same as 8 cores, eight times the credits.
- L4: 10.6 steps/s. Ties the best CPU. Slower per credit than 8 cores (0.89 vs 1.09 steps per credit-second).
The 8-core and 16-core runs match the L4 energy and temperature. On 32 and 64 cores the starting potential shifted by under 2%. That is the long-range grid split across cores, not a different system. The rate comparison still holds: the FFT did not get faster as cores were added on this one machine.
2,048 atoms, the small case
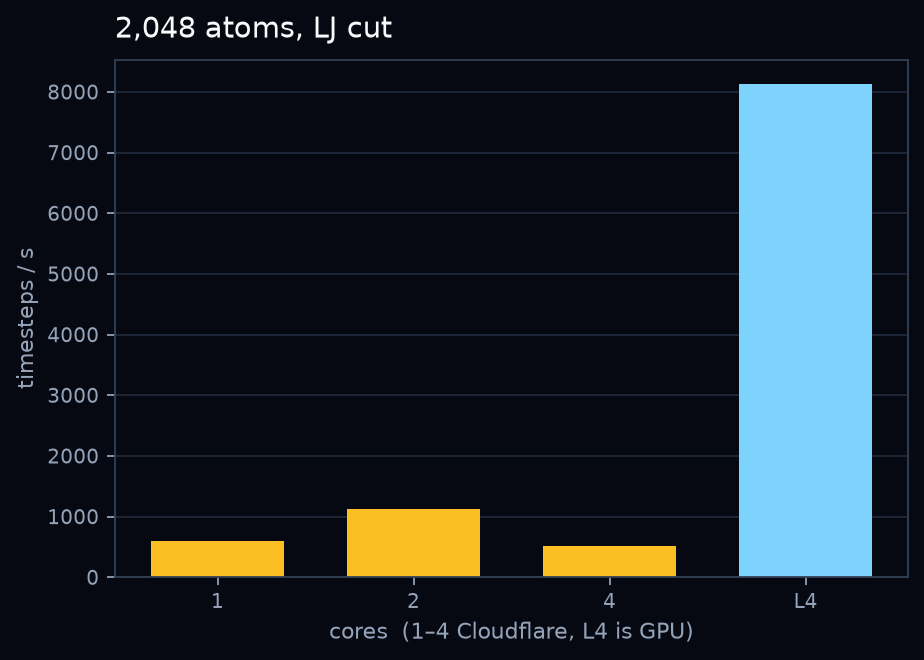
One core: 602 steps/s, pair 83% of the loop. Two cores: 1,124 steps/s. Four cores: 513 steps/s, slower than one core, 77% of the loop in communication. The L4 did 8,123 steps/s, 13.5× the one-core rate, and slightly more steps per credit (677 vs 602). Four cores were the worst buy on this script.
The 256,000-atom box, melting
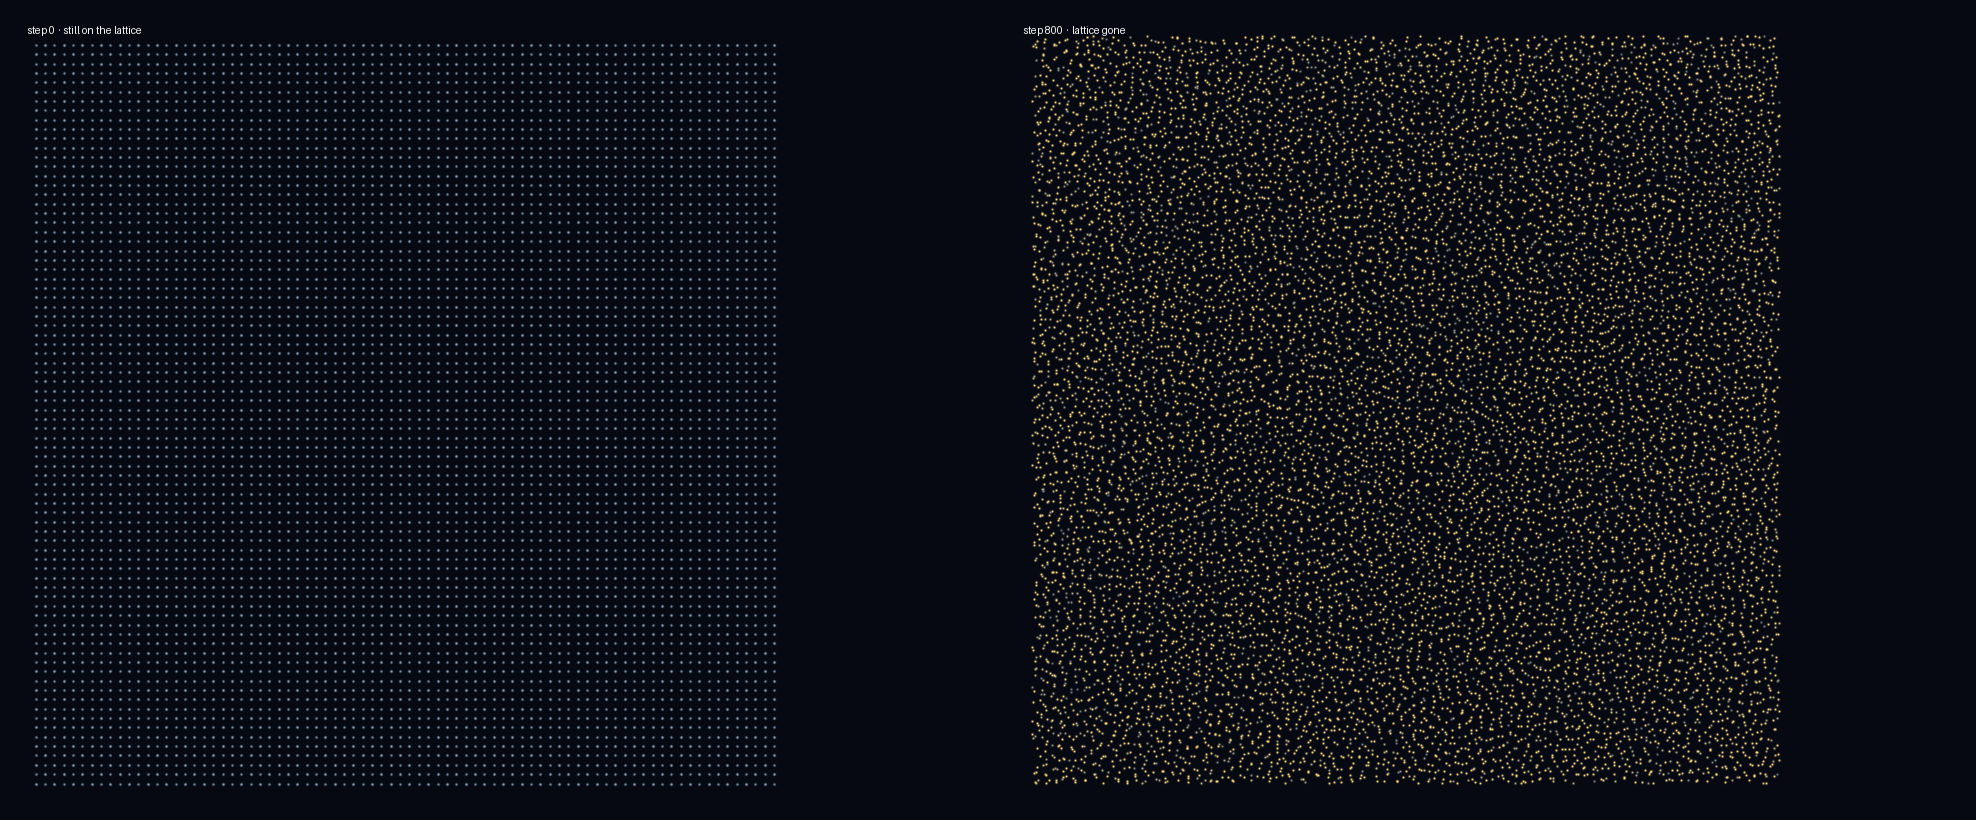
The pictures are a separate run of the same 256,000-atom LJ box, not a timing run. A hot start (T = 2.5) on the FCC lattice, then 800 steps of NVE. Potential energy went from −6.77 to −5.02. Mean displacement from the initial site was 0 at step 0 and 1.23σ at step 800. 89% of atoms had moved more than 0.6σ. The lattice is gone.
How to decide
From these three scripts:
- Short-range LJ at 256,000 atoms: 32 cores beat 8 and beat 64. The L4 beat every CPU size on time and on credits.
- PPPM at 32,000 atoms, this accuracy, this grid: more cores did not pay. Eight cores beat the L4 on credits. The L4 did not beat 32 cores on time.
- LJ at 2,048 atoms: two cores helped. Four cores did not. The L4 was much faster and not more expensive per step than one core.
The picker states the burn rate before you press Run, and it will not start a size your balance cannot cover for one minute. A run that starts and then fails still uses credits for the time the cores were reserved. A job that never gets a machine does not.
Who can pick what
- Free: 1 core.
- Basic: 1–16 cores.
- Pro: 1–64 cores, and GPU.
One wall-hour on 64 cores is 64 CPU-hours. That is most of a Pro month. On the 256,000-atom LJ script, that hour would also have been slower than 32 cores.
This is a single machine, not a multi-node cluster. We do not promise a speedup. The timings above are the reason.
LAMMPS 22 Jul 2025. Cite Thompson et al., Comp. Phys. Comm. 271, 108171 (2022).